Data Engineer resume examples
This page has 12 one-page data engineer resume examples, from an ETL developer and a data integration engineer to AWS, Azure, big data and platform engineers, then senior, staff, lead and principal data engineers and a big data architect. Each one is checked against 6,394 US postings from 1,842 employers, and the note under each sample says which tools, data volumes and pipeline results it puts first.
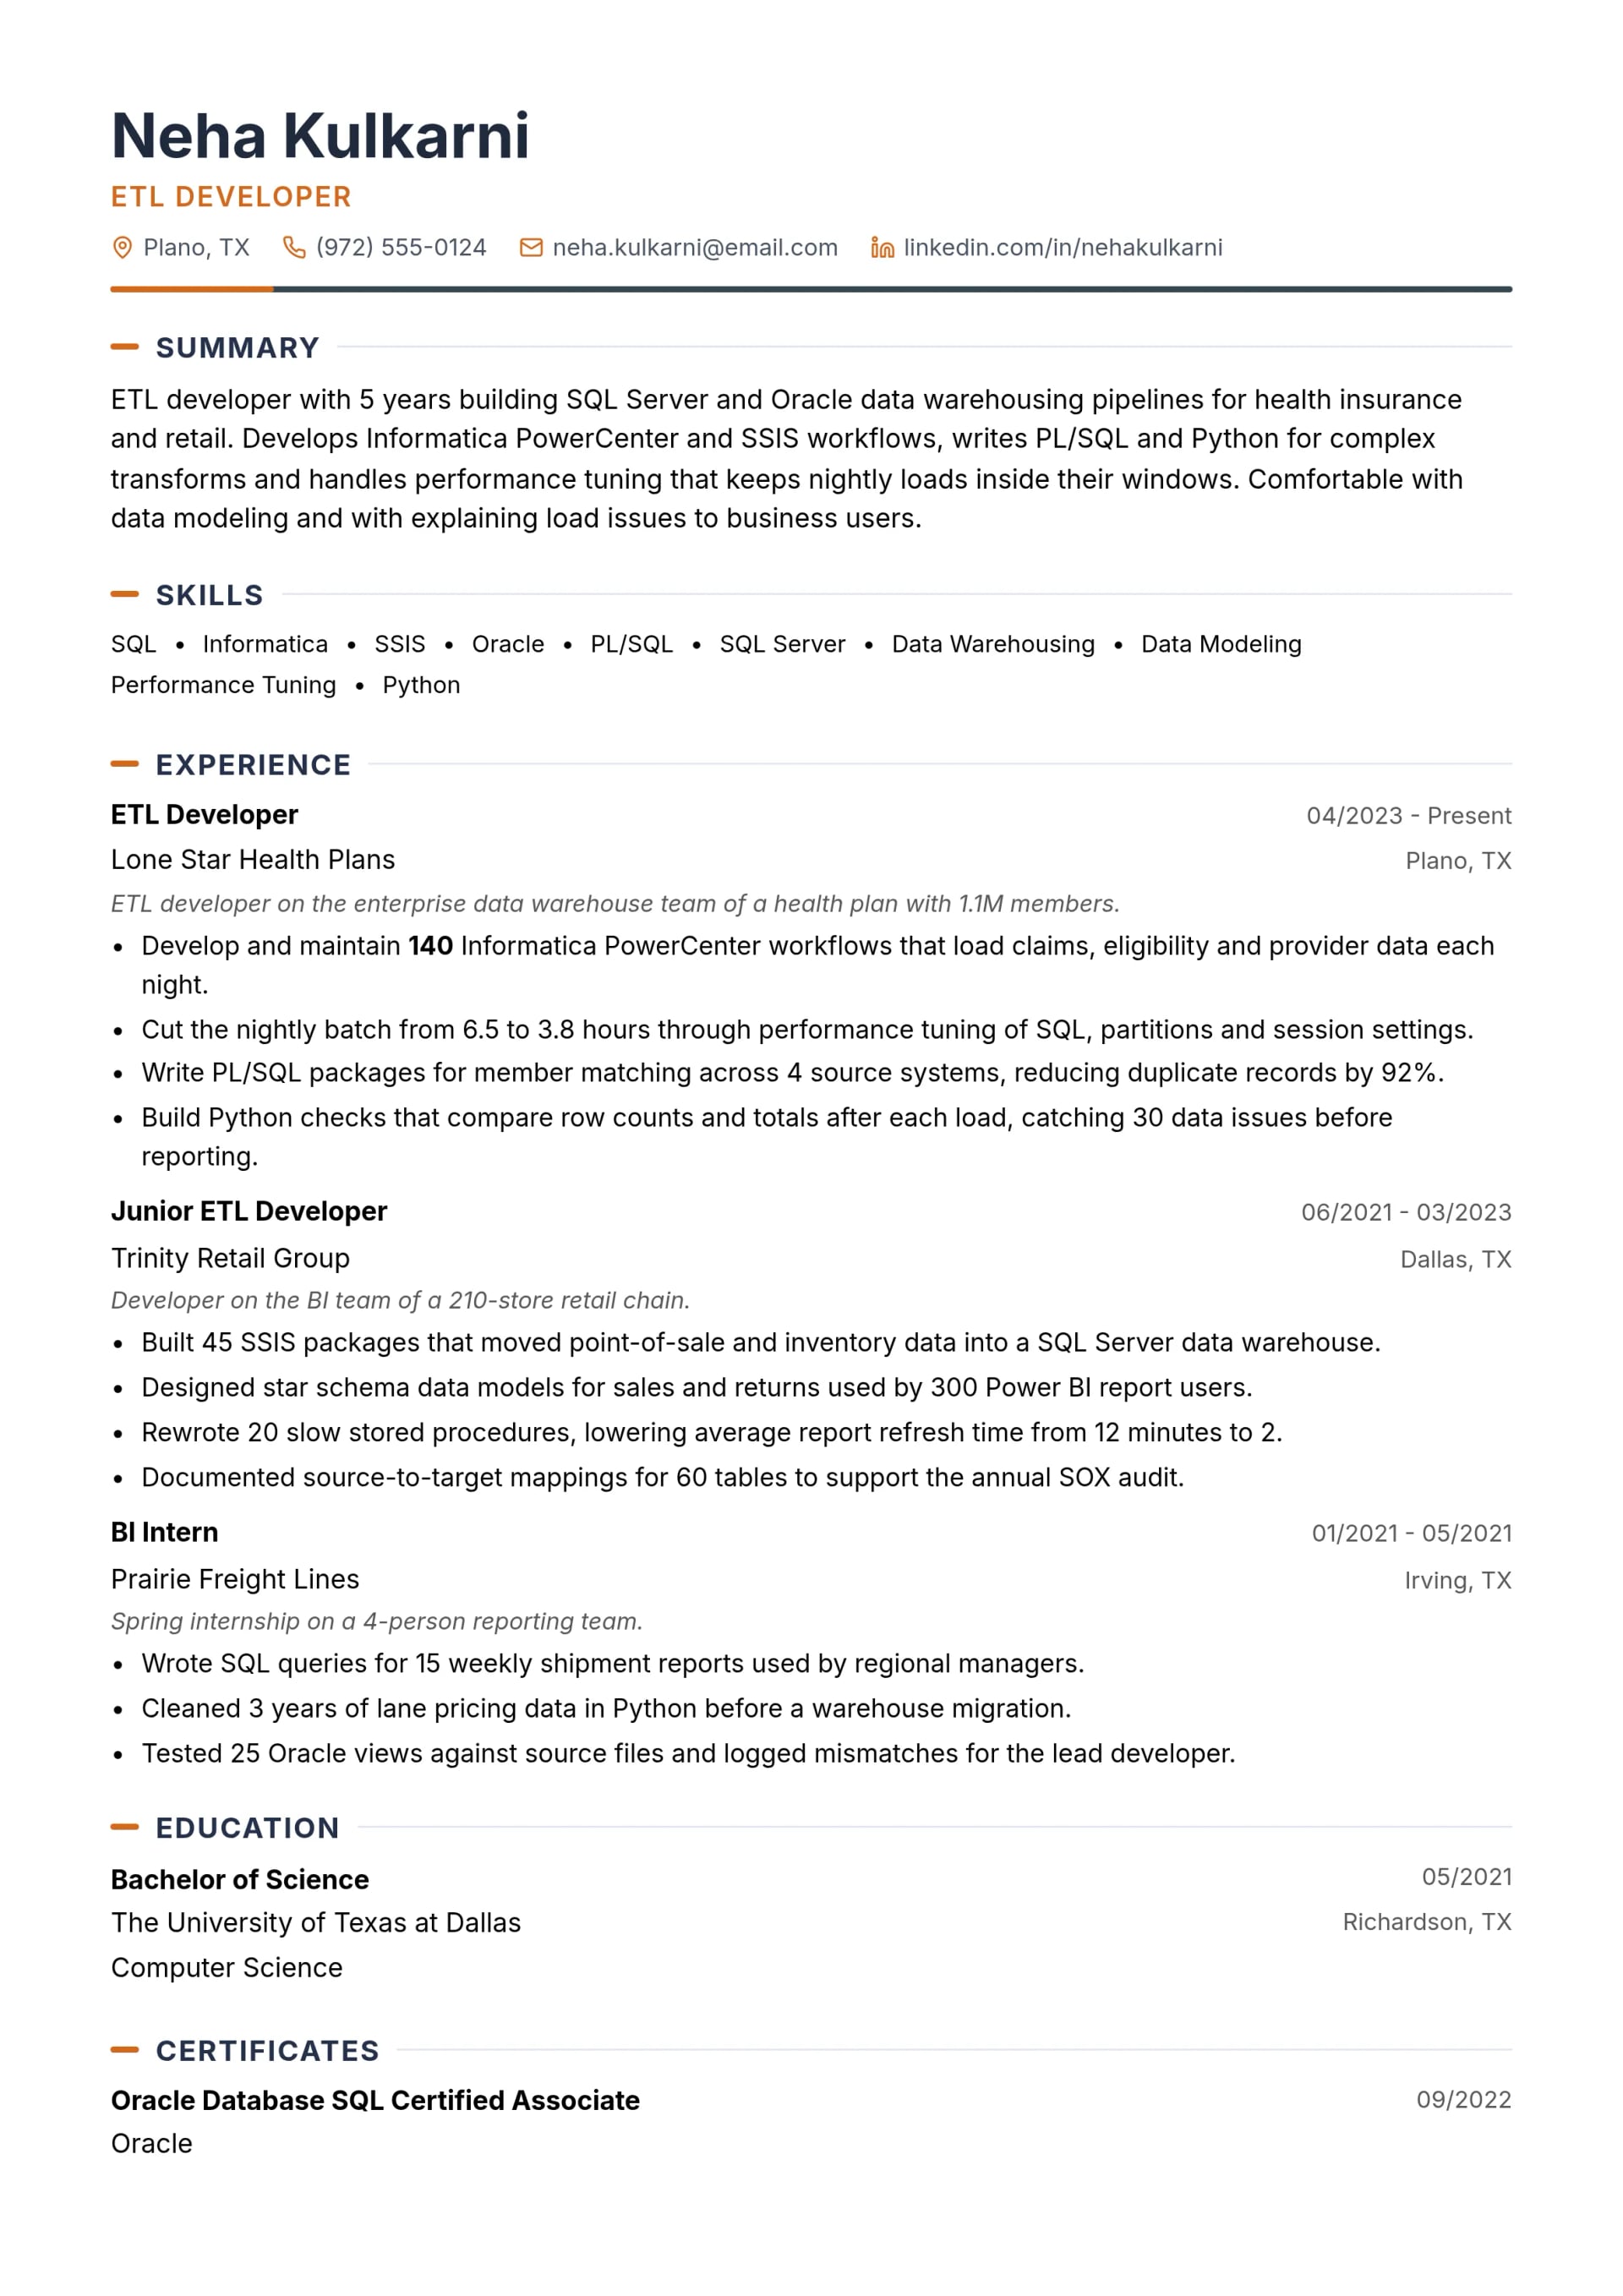
ETL Developer Resume Example
Why this resume works:
- Develop and maintain 140 Informatica PowerCenter workflows that load claims, eligibility and provider data each night.
- Cut the nightly batch from 6.5 to 3.8 hours through performance tuning of SQL, partitions and session settings.
- Write PL/SQL packages for member matching across 4 source systems, reducing duplicate records by 92%.

Data Engineer Resume Example
Why this resume works:
- Build Spark jobs on AWS EMR that load 30M monthly transactions into Snowflake within a 2-hour SLA.
- Develop dbt models and tests for 120 tables, giving finance one source for revenue and fees.
- Run Kafka consumers for 8 event streams, cutting fraud feature delay from 1 hour to 90 seconds.
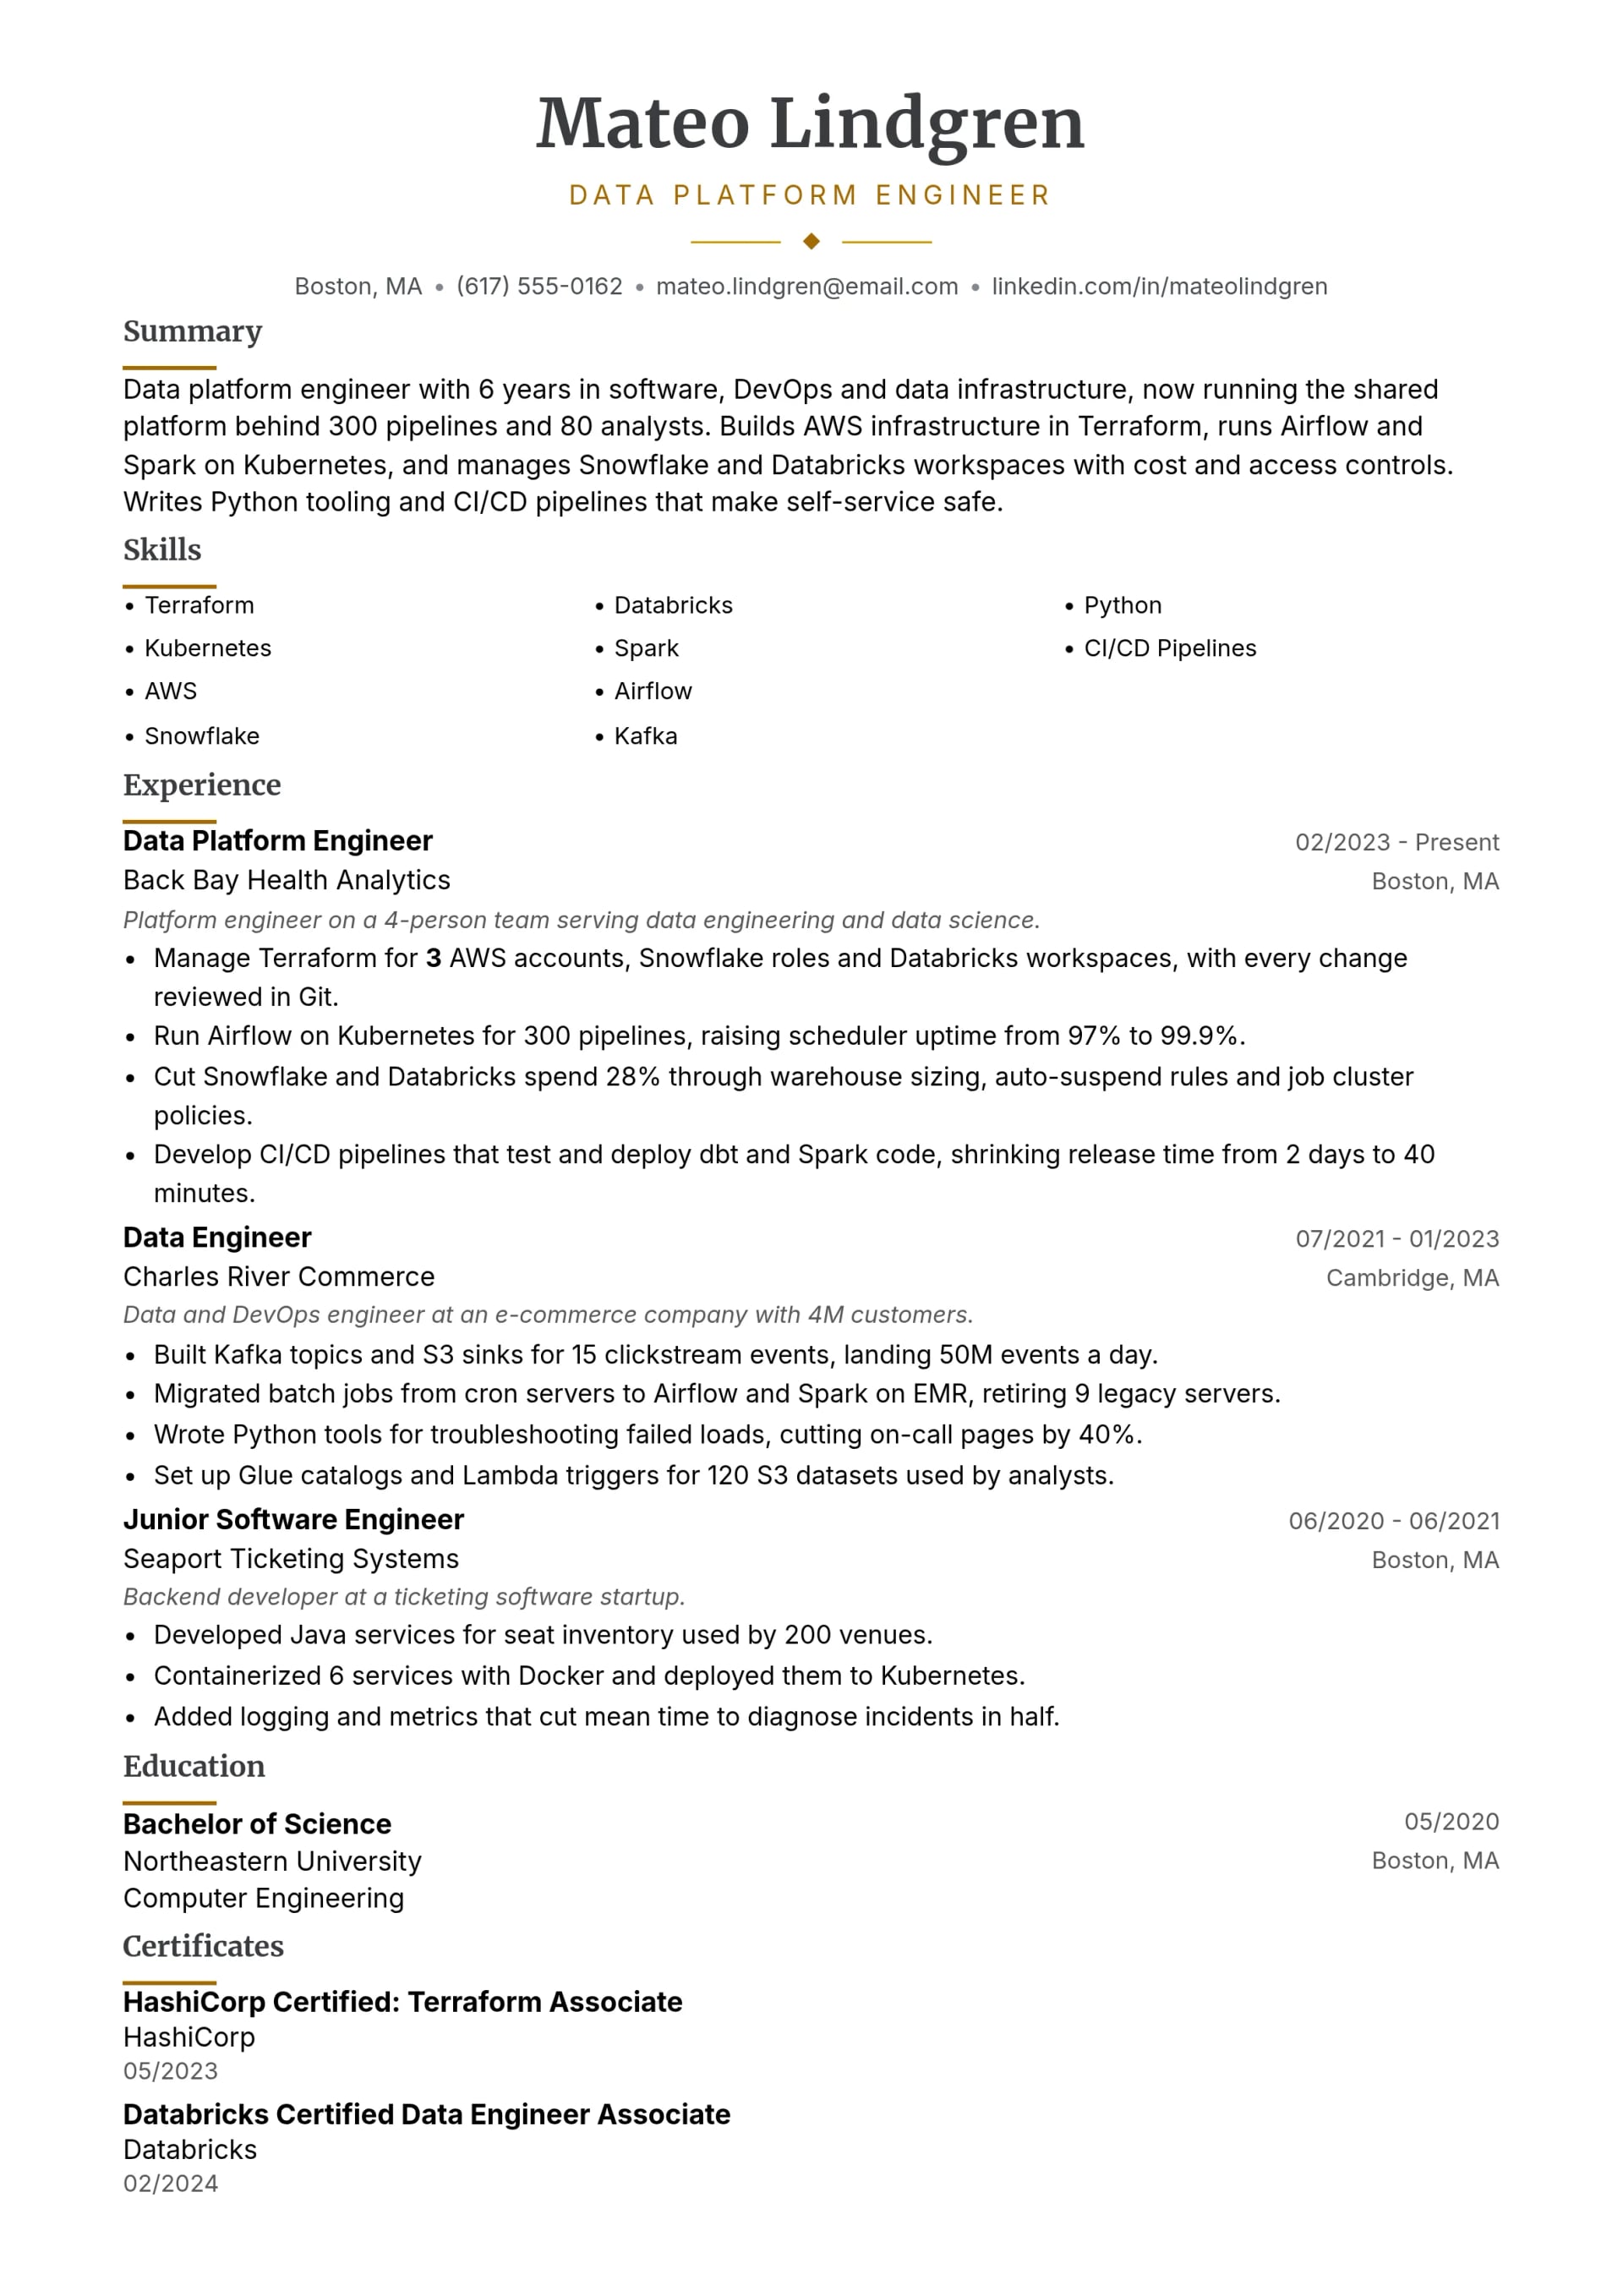
Data Platform Engineer Resume Example
Why this resume works:
- Manage Terraform for 3 AWS accounts, Snowflake roles and Databricks workspaces, with every change reviewed in Git.
- Run Airflow on Kubernetes for 300 pipelines, raising scheduler uptime from 97% to 99.9%.
- Cut Snowflake and Databricks spend 28% through warehouse sizing, auto-suspend rules and job cluster policies.
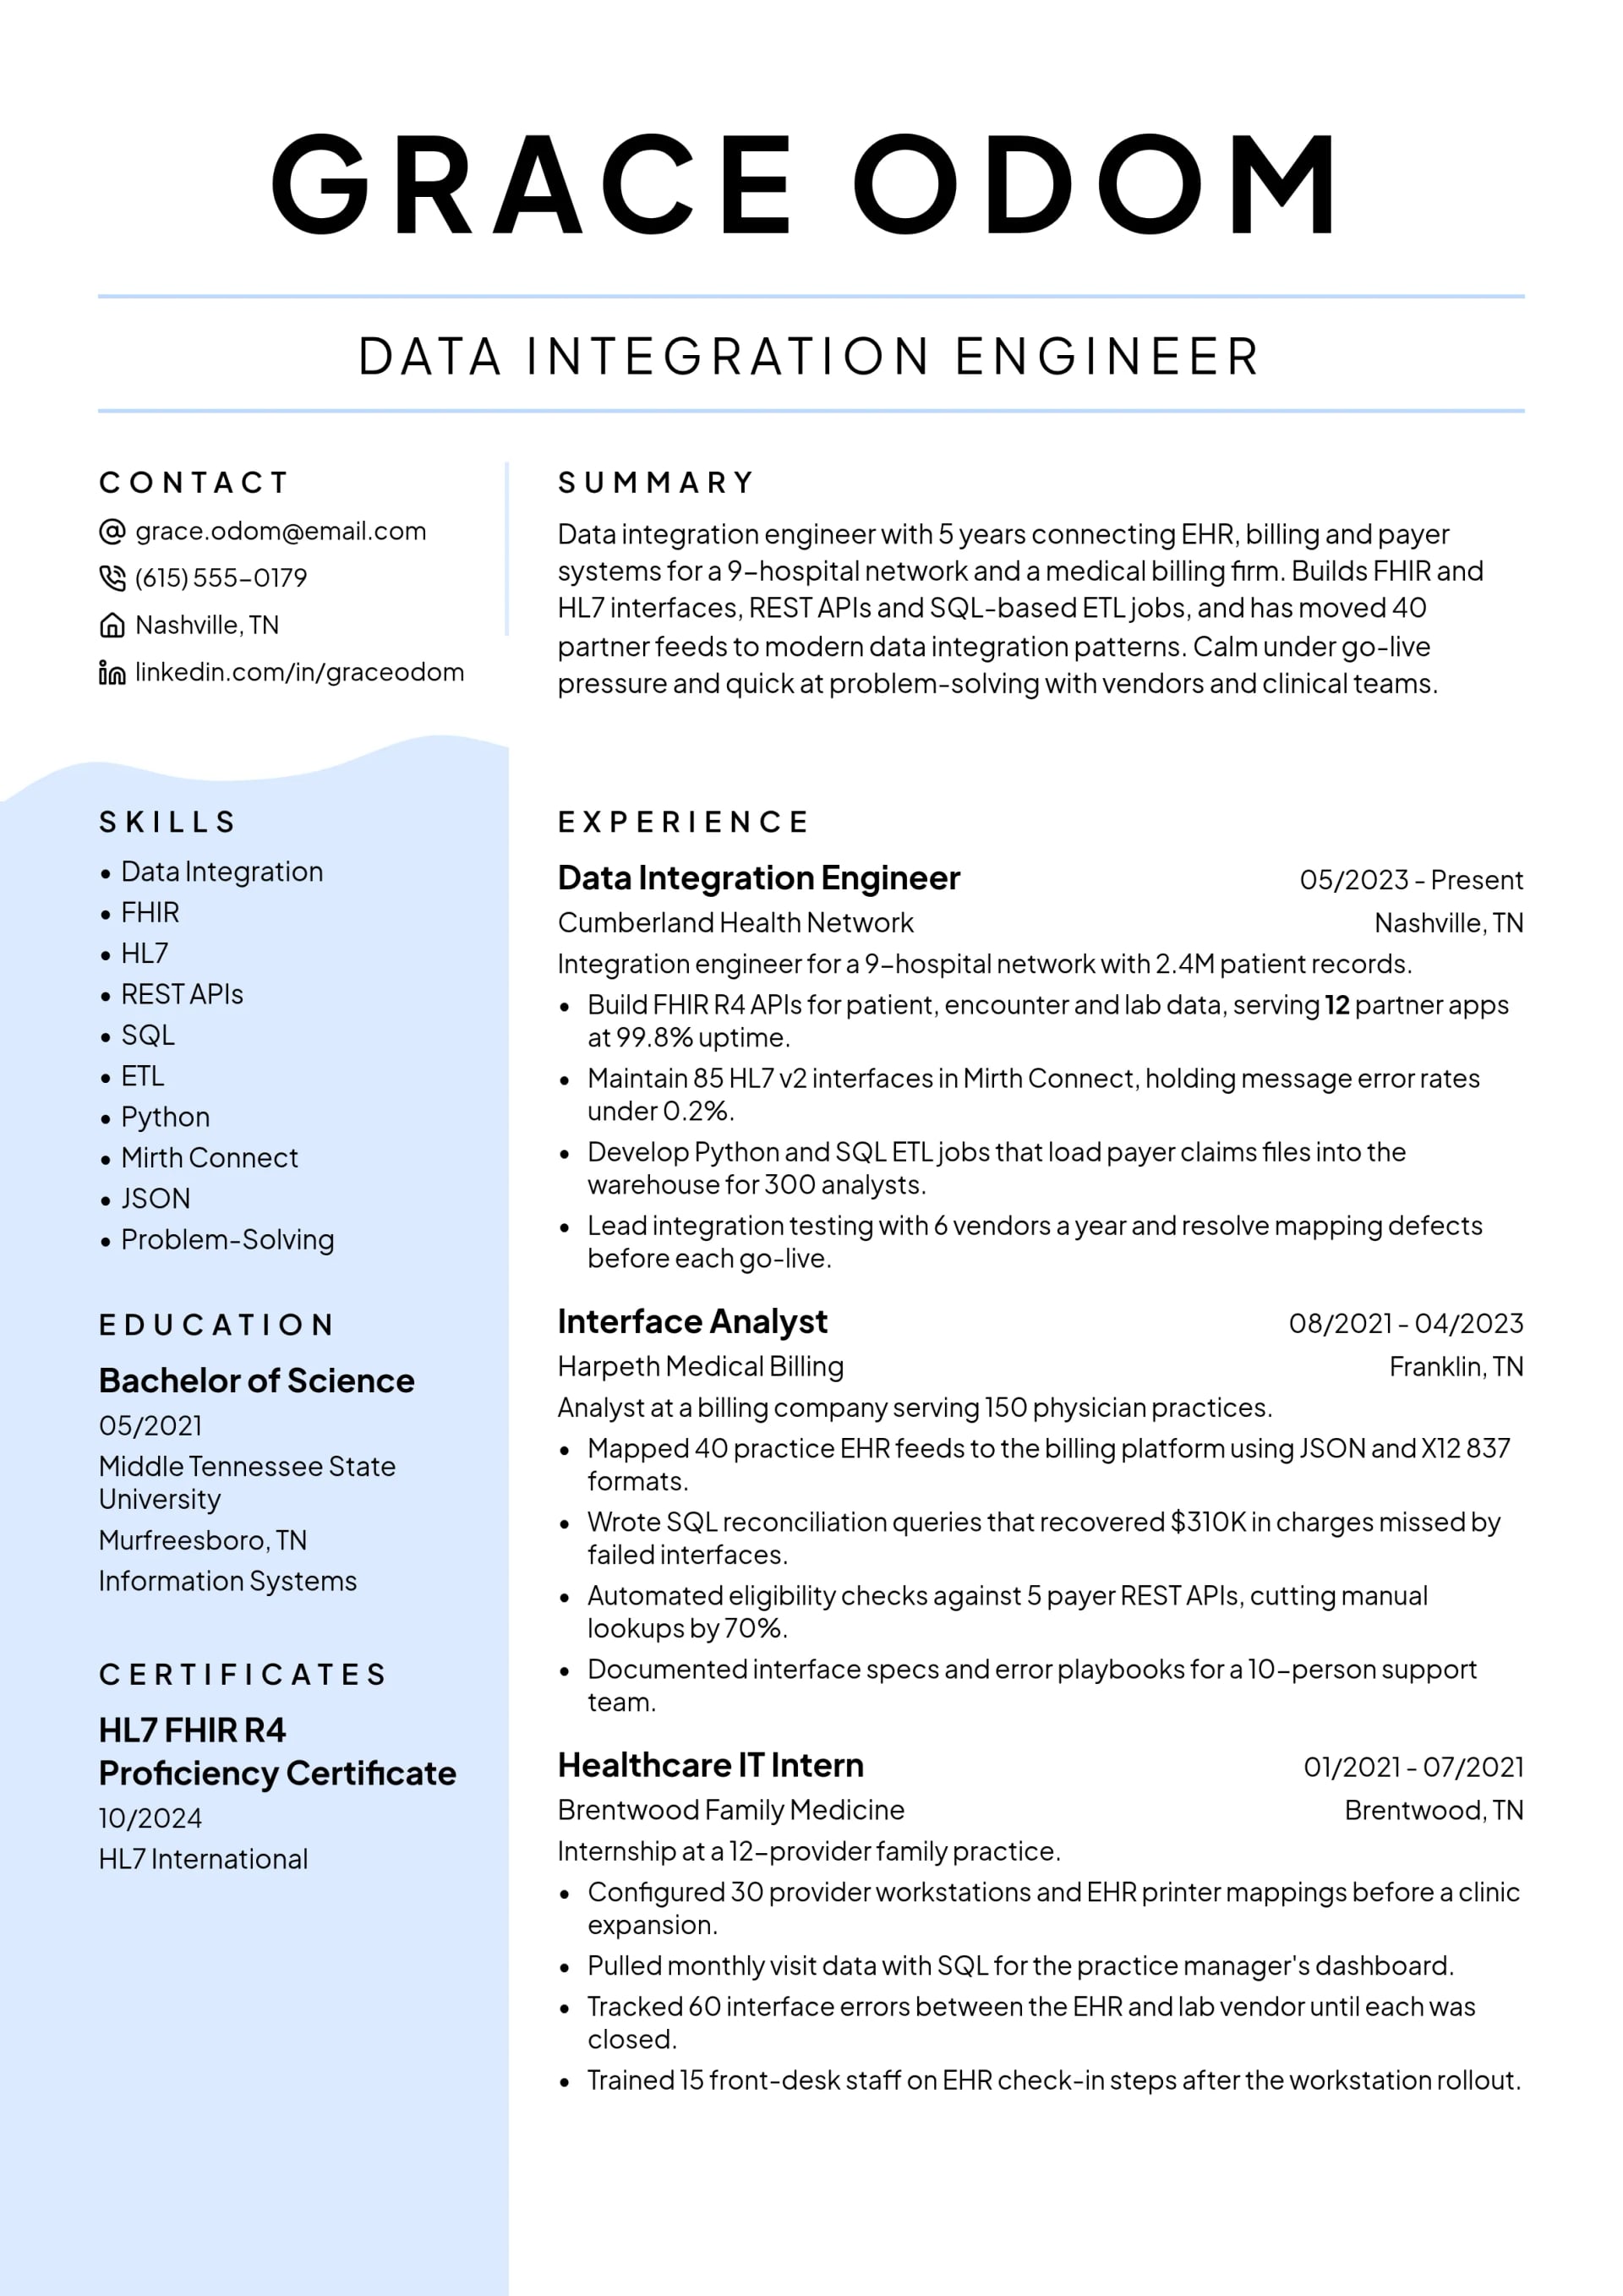
Data Integration Engineer Resume Example
Why this resume works:
- Build FHIR R4 APIs for patient, encounter and lab data, serving 12 partner apps at 99.8% uptime.
- Maintain 85 HL7 v2 interfaces in Mirth Connect, holding message error rates under 0.2%.
- Develop Python and SQL ETL jobs that load payer claims files into the warehouse for 300 analysts.

Big Data Engineer Resume Example
Why this resume works:
- Develop Scala Spark jobs that process 4 TB of card and deposit data a day for fraud and risk models.
- Run Kafka streams for 20 real-time feeds, sending card swipes to fraud scoring within 3 seconds.
- Lead the move of 600 Hive tables from an on-premises Hadoop cluster to EMR and S3, saving $1.1M a year.
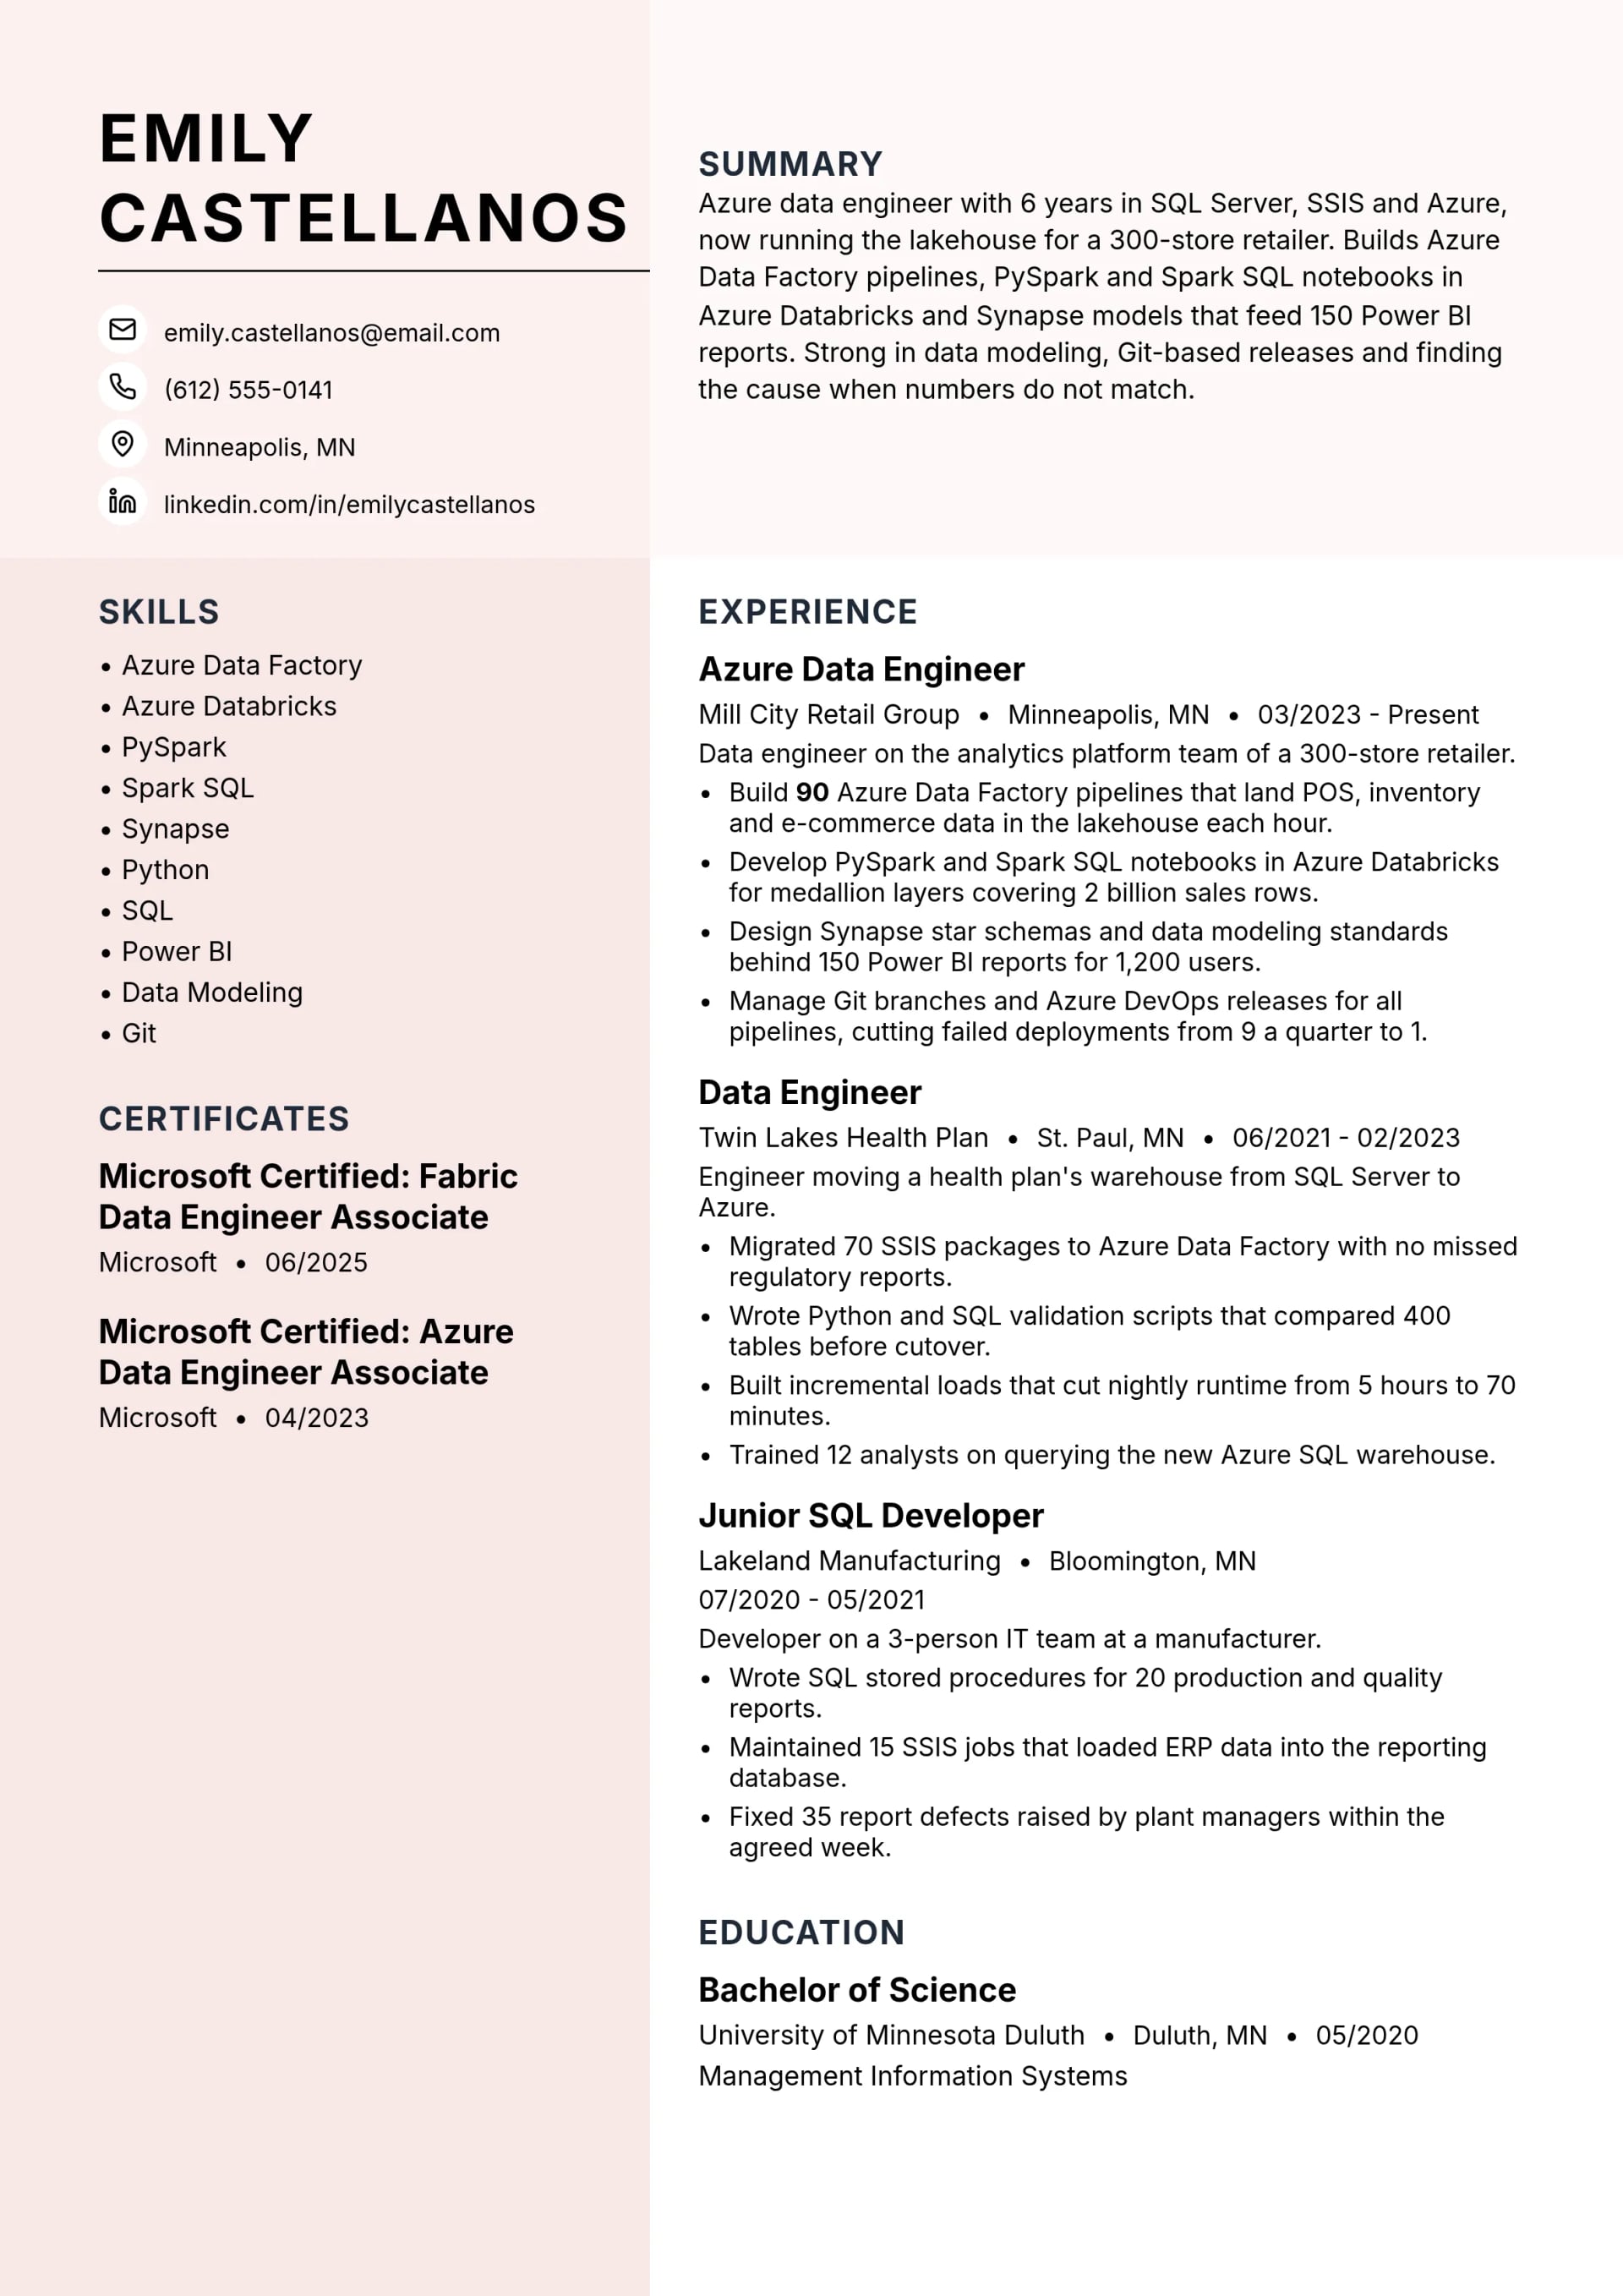
Azure Data Engineer Resume Example
Why this resume works:
- Build 90 Azure Data Factory pipelines that land POS, inventory and e-commerce data in the lakehouse each hour.
- Develop PySpark and Spark SQL notebooks in Azure Databricks for medallion layers covering 2 billion sales rows.
- Design Synapse star schemas and data modeling standards behind 150 Power BI reports for 1,200 users.

AWS Data Engineer Resume Example
Why this resume works:
- Build AWS Glue PySpark jobs that turn 1.5 TB of daily booking and search logs into S3 Parquet tables.
- Design Redshift models for bookings and pricing that serve 250 analysts with sub-10-second queries.
- Orchestrate 70 workflows with Step Functions and Lambda, with CloudWatch alarms that end silent failures.

Senior Data Engineer Resume Example
Why this resume works:
- Own a 40 TB Snowflake platform serving 200 customer dashboards, meeting a 99.9% freshness SLA in 2025.
- Lead the dbt project of 600 models, adding tests and contracts that cut data incidents by 65%.
- Build Kafka and Spark streaming jobs that cut event-to-dashboard delay from 30 minutes to 2.
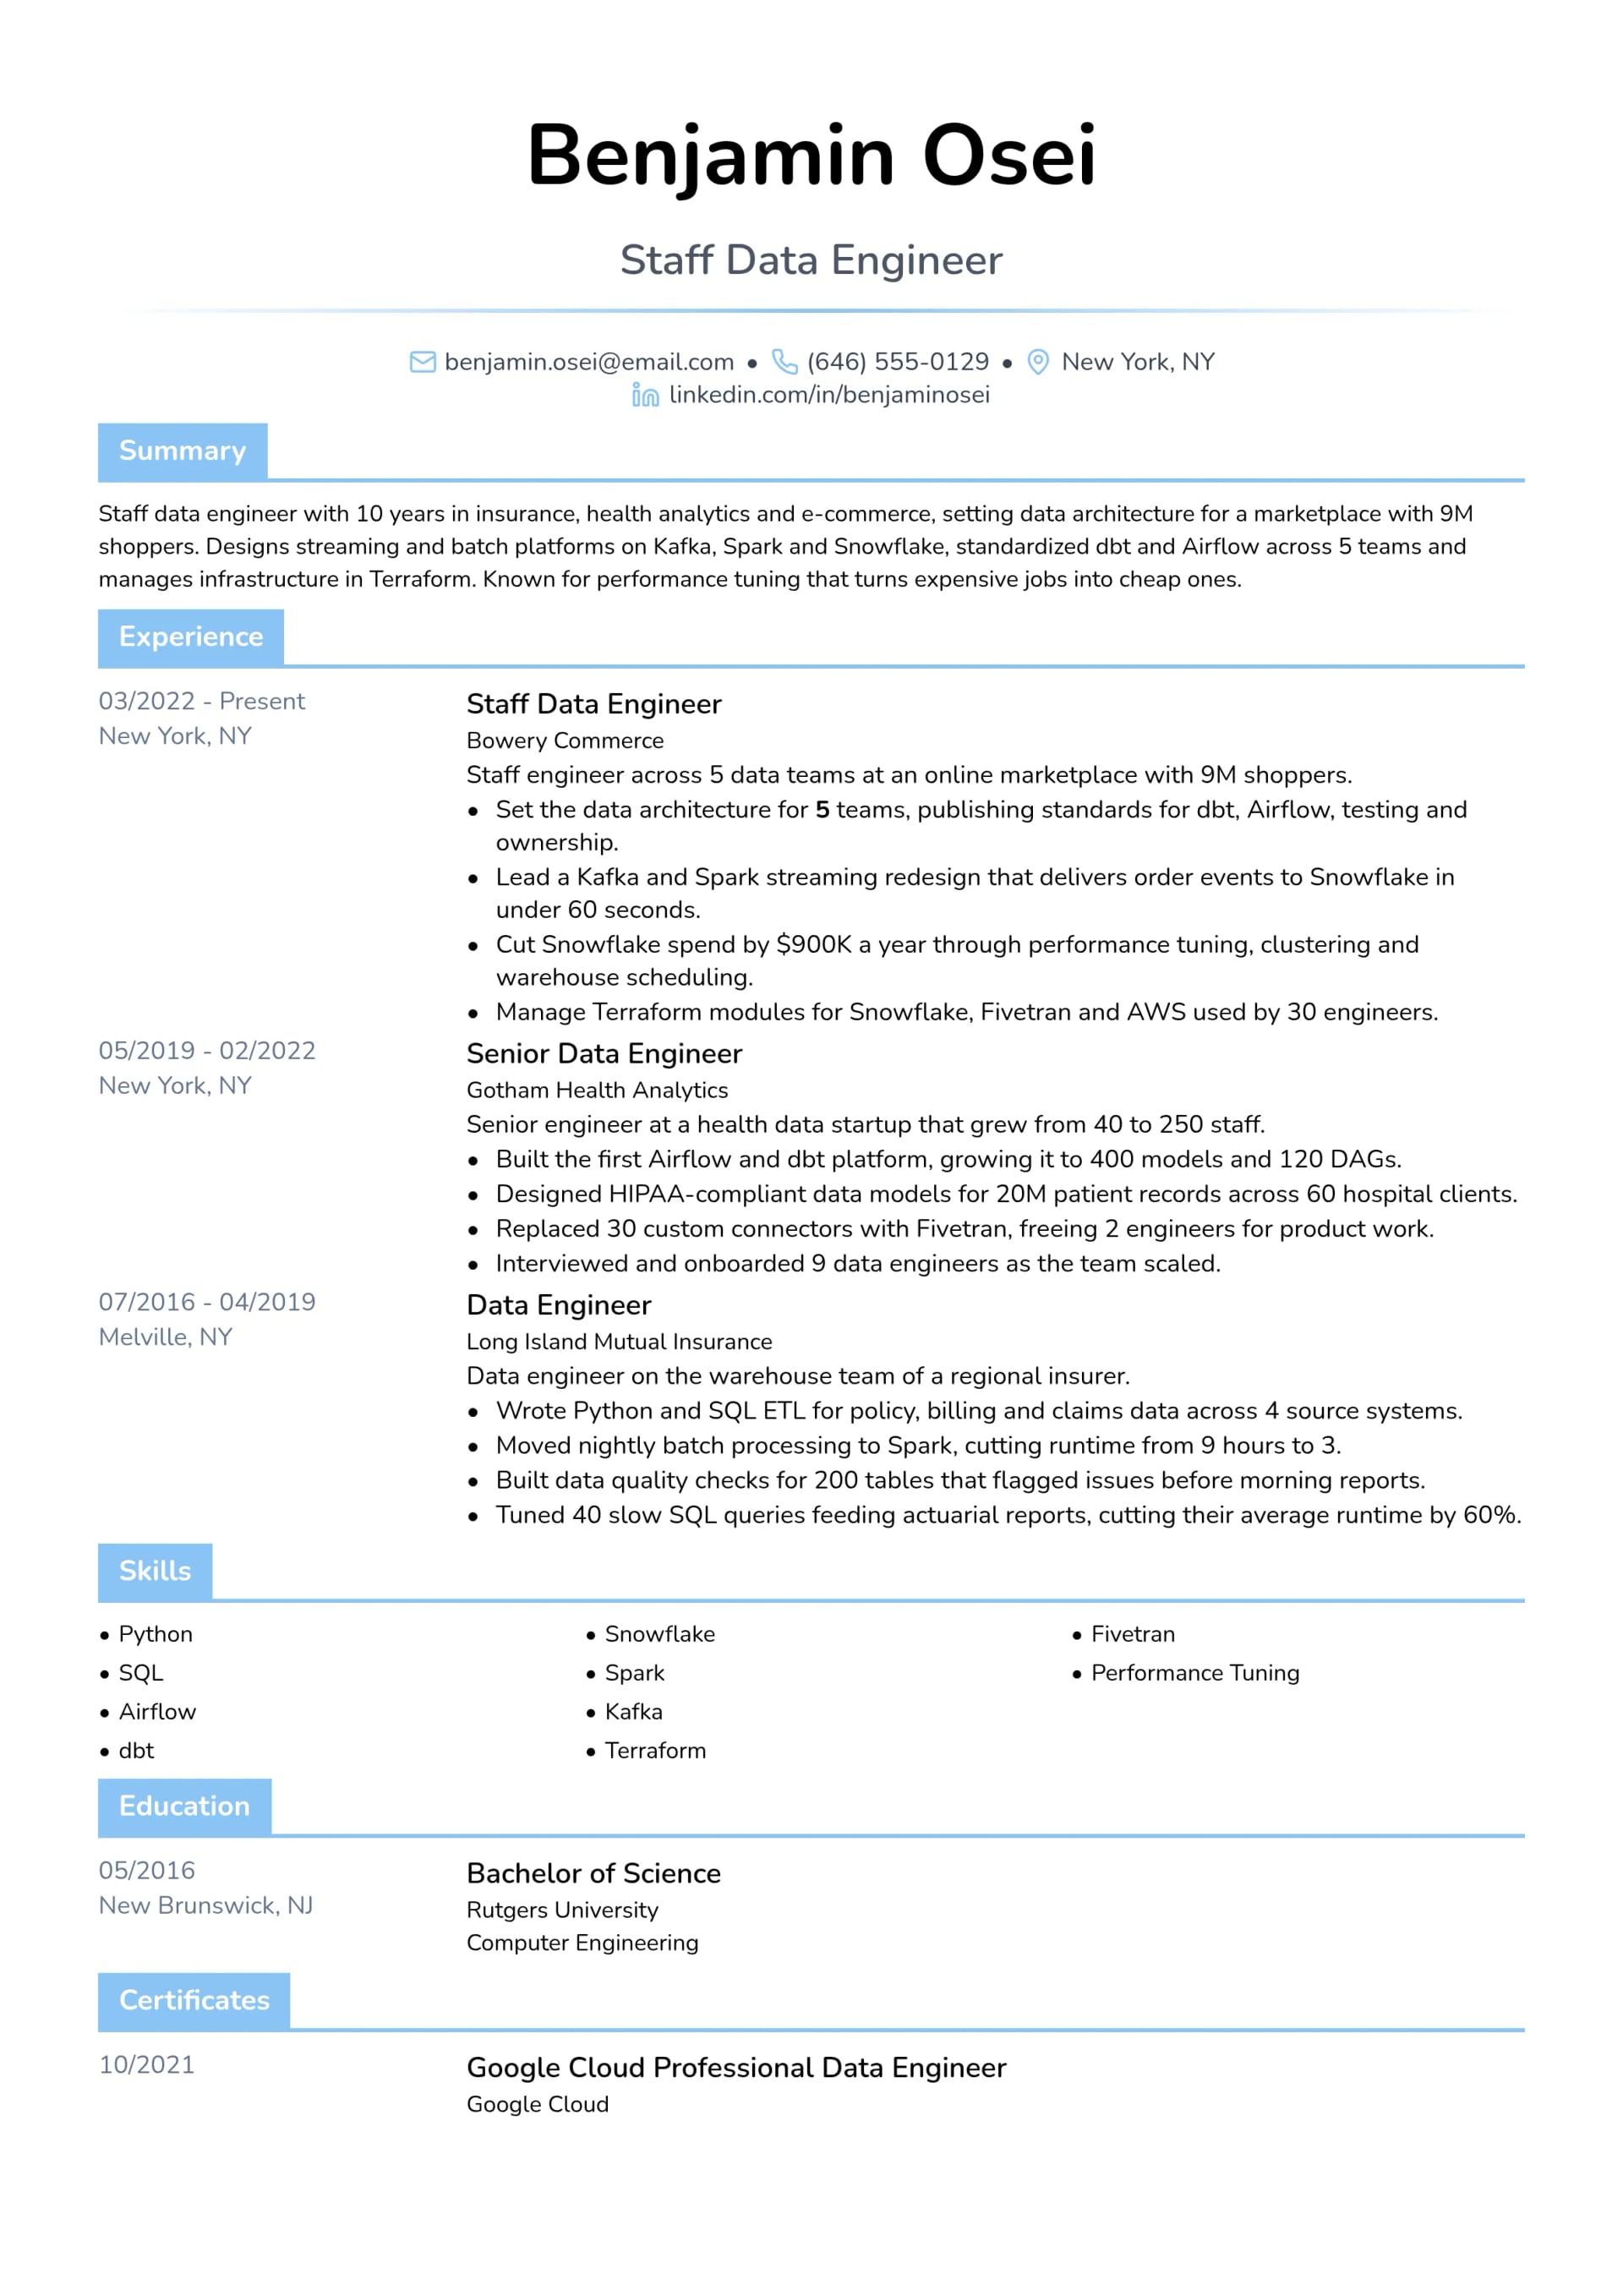
Staff Data Engineer Resume Example
Why this resume works:
- Set the data architecture for 5 teams, publishing standards for dbt, Airflow, testing and ownership.
- Lead a Kafka and Spark streaming redesign that delivers order events to Snowflake in under 60 seconds.
- Cut Snowflake spend by $900K a year through performance tuning, clustering and warehouse scheduling.

Lead Data Engineer Resume Example
Why this resume works:
- Lead a team of 7 data engineers delivering 40 pipeline projects a year on Databricks and AWS.
- Set data quality rules and monitoring for 900 tables, cutting reported data defects by 70%.
- Design the lakehouse data modeling approach for clinical, claims and finance domains used by 400 analysts.

Principal Data Engineer Resume Example
Why this resume works:
- Set the data architecture for 4 teams and 25 engineers, from Kafka ingestion to Snowflake serving.
- Lead a lineage program across 3,000 tables, cutting time to trace a broken metric from days to minutes.
- Design Apache Spark and Databricks patterns for 800 jobs, lowering compute cost by 35%.
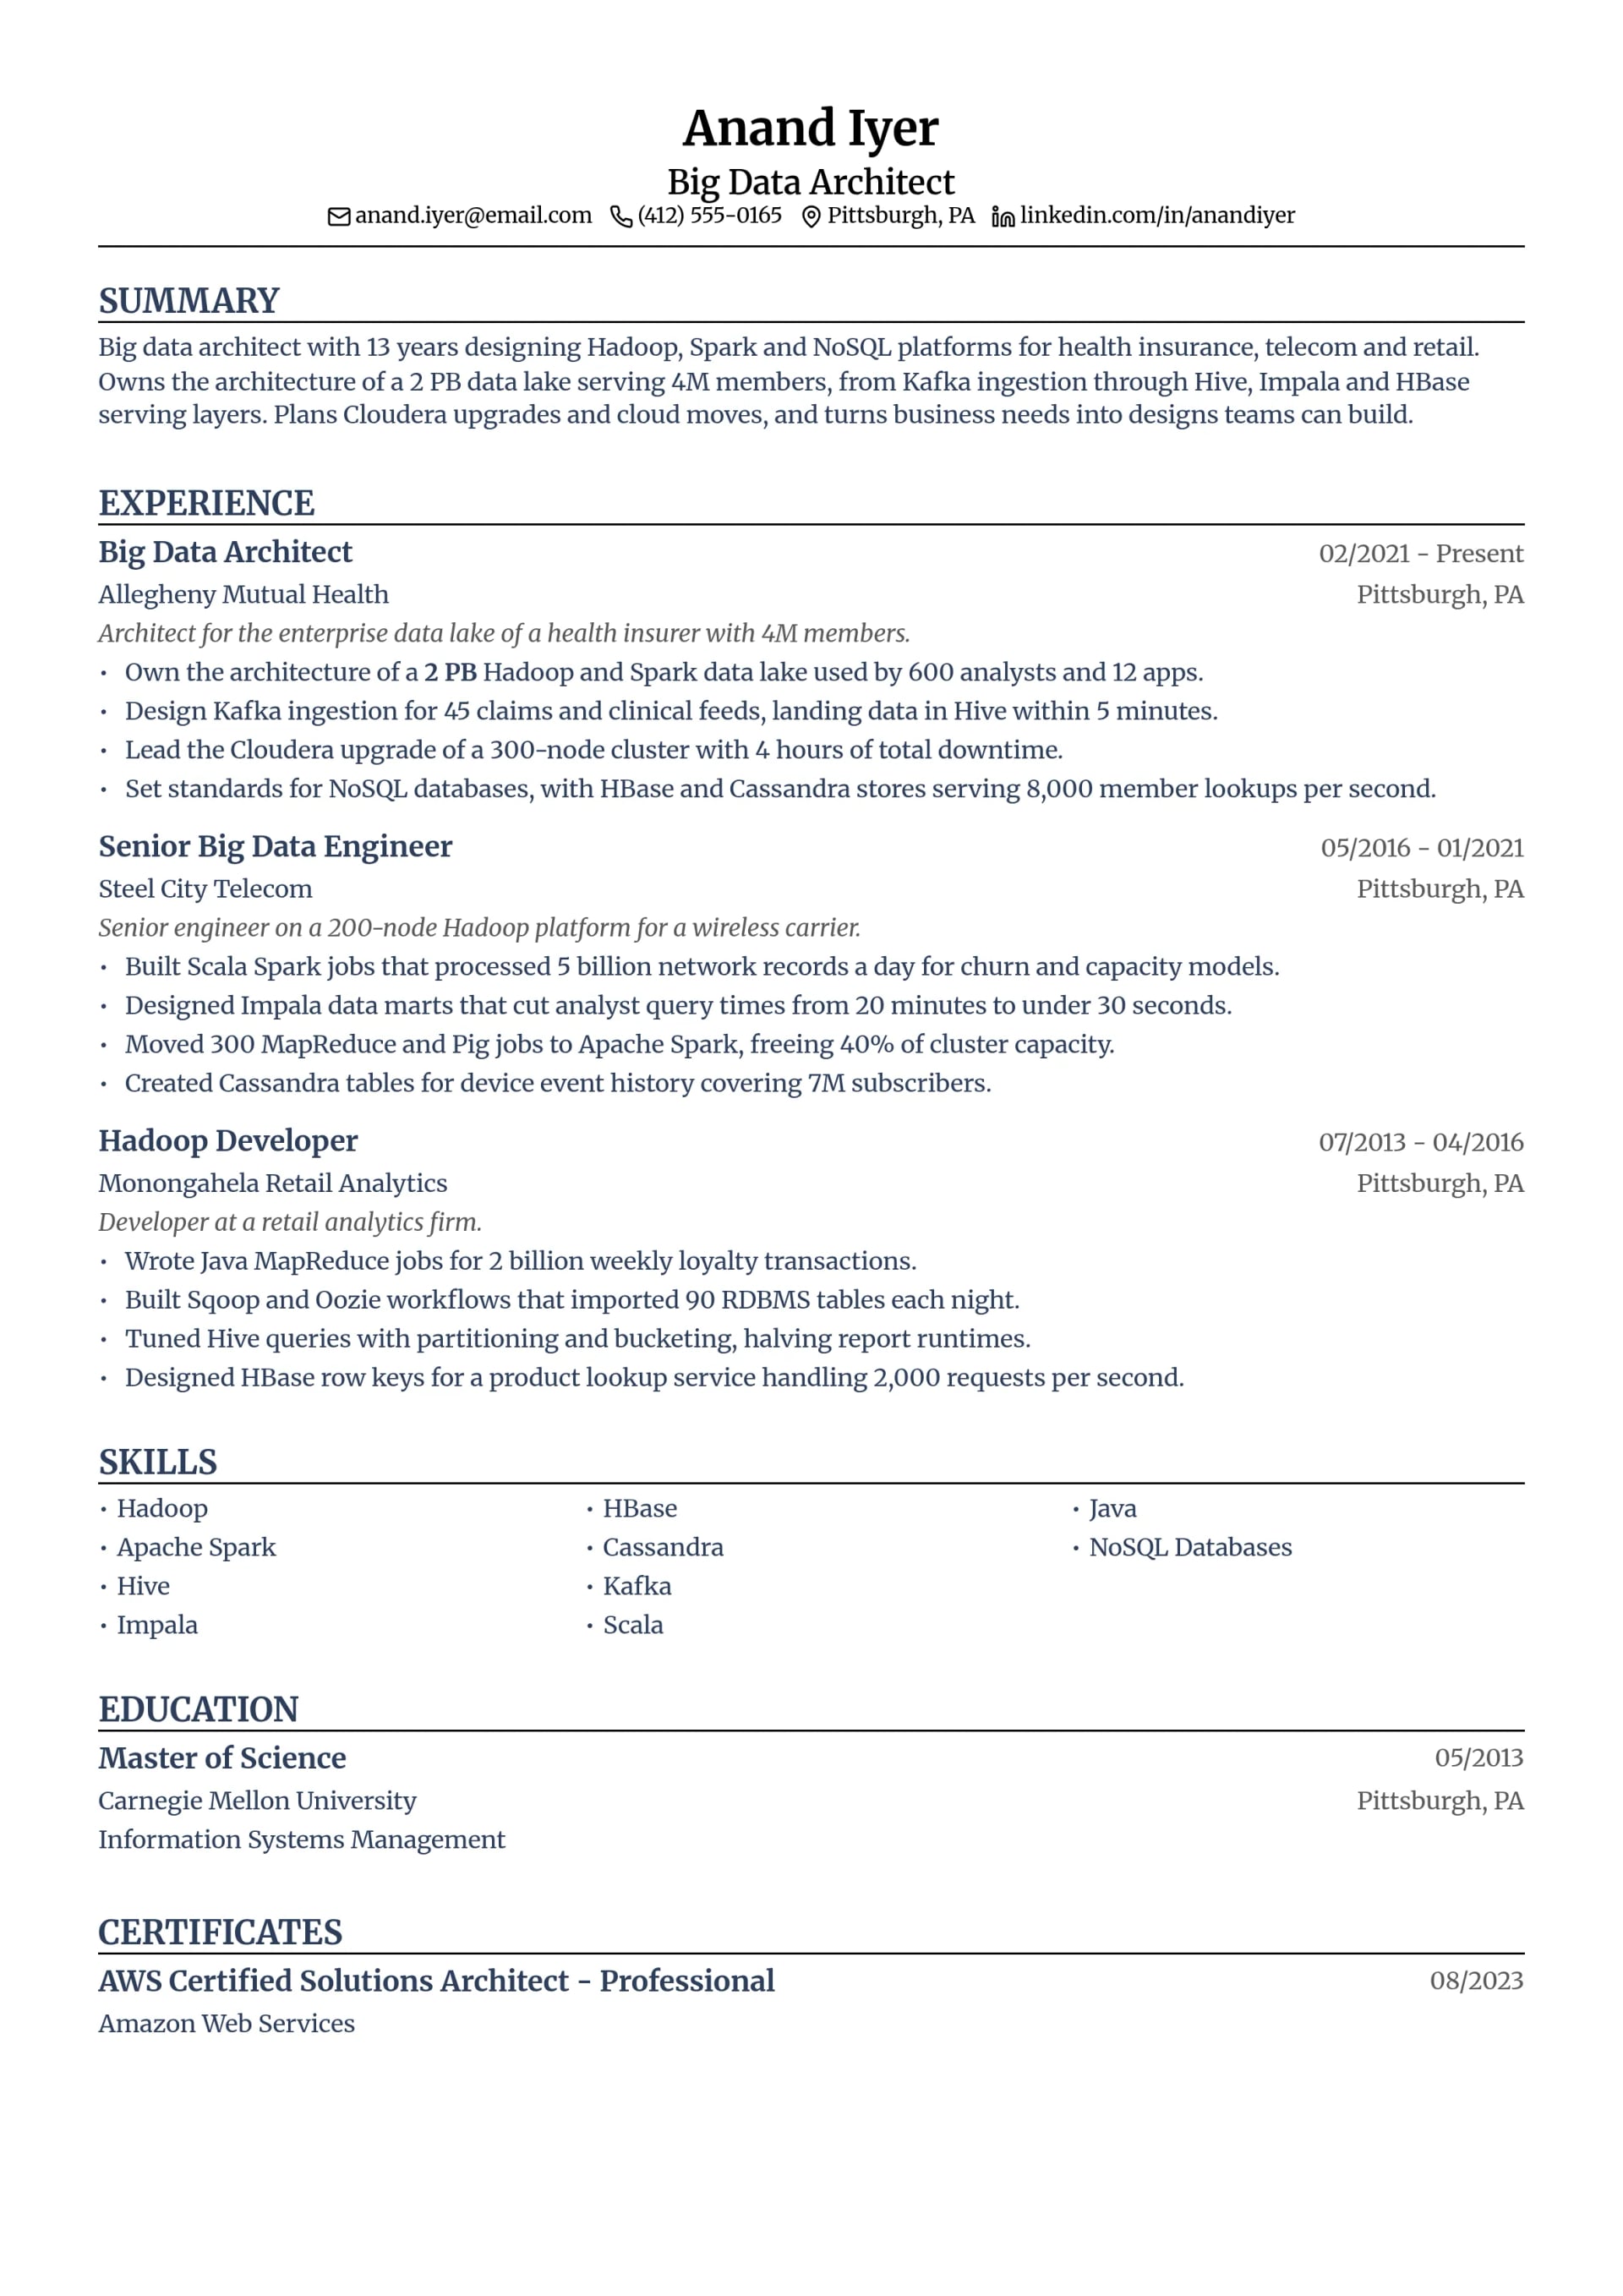
Big Data Architect Resume Example
Why this resume works:
- Own the architecture of a 2 PB Hadoop and Spark data lake used by 600 analysts and 12 apps.
- Design Kafka ingestion for 45 claims and clinical feeds, landing data in Hive within 5 minutes.
- Lead the Cloudera upgrade of a 300-node cluster with 4 hours of total downtime.
What employers ask for in data engineer job postings
Data Engineer job postings in the US, October 2026
- 6,394
- active US job postings
- 1,842
- employers hiring
- 4 yr
- median experience asked
- 8%
- ask for 1 year or less
Technical skills and tools employers name
| Skill | Share of postings |
|---|---|
| sql | 51% |
| python | 56% |
| spark | 28% |
| data engineering | 17% |
| etl | 17% |
| databricks | 18% |
| data modeling | 19% |
| aws | 25% |
| snowflake | 17% |
| airflow | 14% |
Make sure your resume shows
- 5+ years in data engineering, data science or data analytics (50% of employers)
- Bachelor's or master's degree in computer science, information systems or engineering (46% of employers)
- Strong Python programming and SQL (42% of employers)
- Strong analytical, problem-solving and communication skills (28% of employers)
- Cloud platform experience on AWS, Azure or Google Cloud (15% of employers)
- Git, CI/CD pipelines and DevOps practice (14% of employers)
- Apache Spark, PySpark or similar distributed processing (13% of employers)
- Data warehousing, data modeling and schema design (13% of employers)
Duties to build your bullet points around
What employers write most often under responsibilities. Show each one with a result (numbers, scale, outcome), not a copy of the duty.
- Design, build and maintain scalable data pipelines and ETL/ELT processes (37%)
- Keep data accurate, complete and secure through governance practice (24%)
- Work with data scientists, analysts and business teams on data needs (22%)
- Monitor, troubleshoot and tune pipeline performance (10%)
- Mentor junior engineers and lead technical work across projects (8%)
- Write technical documentation, data flow diagrams and runbooks (6%)
The examples on this page, in job postings
| Example | US postings | Median years asked | Skills that set this role apart |
|---|---|---|---|
| ETL Developer | 190 | 5 | – |
| Data Engineer | 984 | 3 | – |
| Data Platform Engineer | 59 | 4.5 | – |
| Data Integration Engineer | 30 | 4.5 | – |
| Big Data Engineer | 119 | 3 | hive, hadoop, hbase, pig |
| Azure Data Engineer | 73 | 5 | – |
| AWS Data Engineer | 77 | 6 | – |
| Senior Data Engineer | 774 | 5 | – |
| Staff Data Engineer | 73 | 7 | – |
| Lead Data Engineer | 144 | 5 | – |
| Principal Data Engineer | 87 | 8 | – |
| Big Data Architect | 79 | 3 | – |
Which job title to put on your resume: the titles employers use most, so recruiters and applicant tracking systems search for them: Data Engineer (437 employers), Senior Data Engineer (408 employers), Sr. Data Engineer (93 employers), Lead Data Engineer (87 employers), ETL Developer (83 employers).
Source: Owlapply analysis of active US job postings, October 2026. Requirements and duties are grouped by meaning from the postings' own bullet lists and counted once per employer.
Advertised pay, experience and the skills employers ask for: Data Engineer pay and requirements.
Check your data engineer resume against a real job posting
- Paste a data engineer job posting into the job match score tool to see which of its skills your resume is missing.
- Upload your resume to the ATS resume checker to read the text an applicant tracking system gets from it.
Data Engineer resume sample (text you can copy)
This is the text of the ETL Developer example above. Paste it into the resume builder and replace the details with your own.
How to write a data engineer resume
Write a data engineer resume summary
- Name your stack in the first two lines: language, warehouse or lakehouse, processing engine and orchestrator, such as Python, Snowflake, Spark and Airflow.
- Say what kind of data you move and how much, such as payments events, claims files or clickstream at TB a day, because scale decides fit.
- State batch, streaming or both; postings that ask for Kafka or real-time features read a batch-only summary as a miss.
- For senior, staff and principal roles, add the scope you own: the platform, the number of teams or engineers and the standards you set.
Write data engineer experience bullets
- Show pipeline results: data volume, load time against the SLA, success rate and freshness.
- Show cost and speed gains with before-and-after numbers, such as a batch cut from hours to minutes or warehouse spend reduced.
- Show data quality work in counts: tests added, tables covered and incidents or defects cut.
- Name who used your data, such as analysts, dashboards, ML models or customer reports, so the reader sees the business reason.
Pick the skills for a data engineer resume
- Python appears in about 56% of postings and SQL in about 51%; put both first and show each in a bullet.
- Spark (about 28%), AWS (about 25%), data modeling (about 19%), Java and Databricks (about 18% each) and ETL and Snowflake (about 17% each) come next; list the ones you have used in production.
- Communication shows up in about 32% of postings and problem-solving in about 20%; prove them with design reviews, stakeholder work or incident fixes.
Do's and don'ts
Do this
- Match the cloud in the posting: an Azure role wants Data Factory, Databricks and Synapse, an AWS role wants Glue, Redshift, S3 and Lambda.
- Give every pipeline a number: rows, TB, jobs, tables or minutes.
- List orchestration and testing tools such as Airflow and dbt, and Git and CI/CD work, since about 14% of employers ask for Git, CI/CD and DevOps practice.
- Show data modeling by name: star schemas, medallion layers or dimensional models.
Avoid this
- Don't list every tool from a course; employers ask about each one in technical screens.
- Don't write "worked on data pipelines" without the source, the target and the result.
- Don't present dashboards or analysis as data engineering; show the pipelines and models behind them.
- Don't leave out older tools such as SSIS, Informatica or Hadoop when the posting names them; ETL developer and big data roles still ask for them.
Related resume examples
- Solutions Architect
- Data Analyst
- Engineering Manager
- Data Scientist
- Database Administrator
- Software Engineer
- Statistician
- GIS Analyst